Introducing You.com Inference Router: Enterprise-grade inference on demand

TL;DR: Inference Router brings enterprise-grade reliability to leading AI models, including top open-weight models. You get at least 99.9% uptime SLA, zero data retention (ZDR) across every model call and web search request, 100% US-hosted infrastructure, and guided onboarding with our engineers. It’s all available on demand, with simple, predictable pricing per model and volume discounts as you scale. Try it in the playground or talk to an engineer to get started.
When you've outgrown experimentation, and want to scale up flexibly
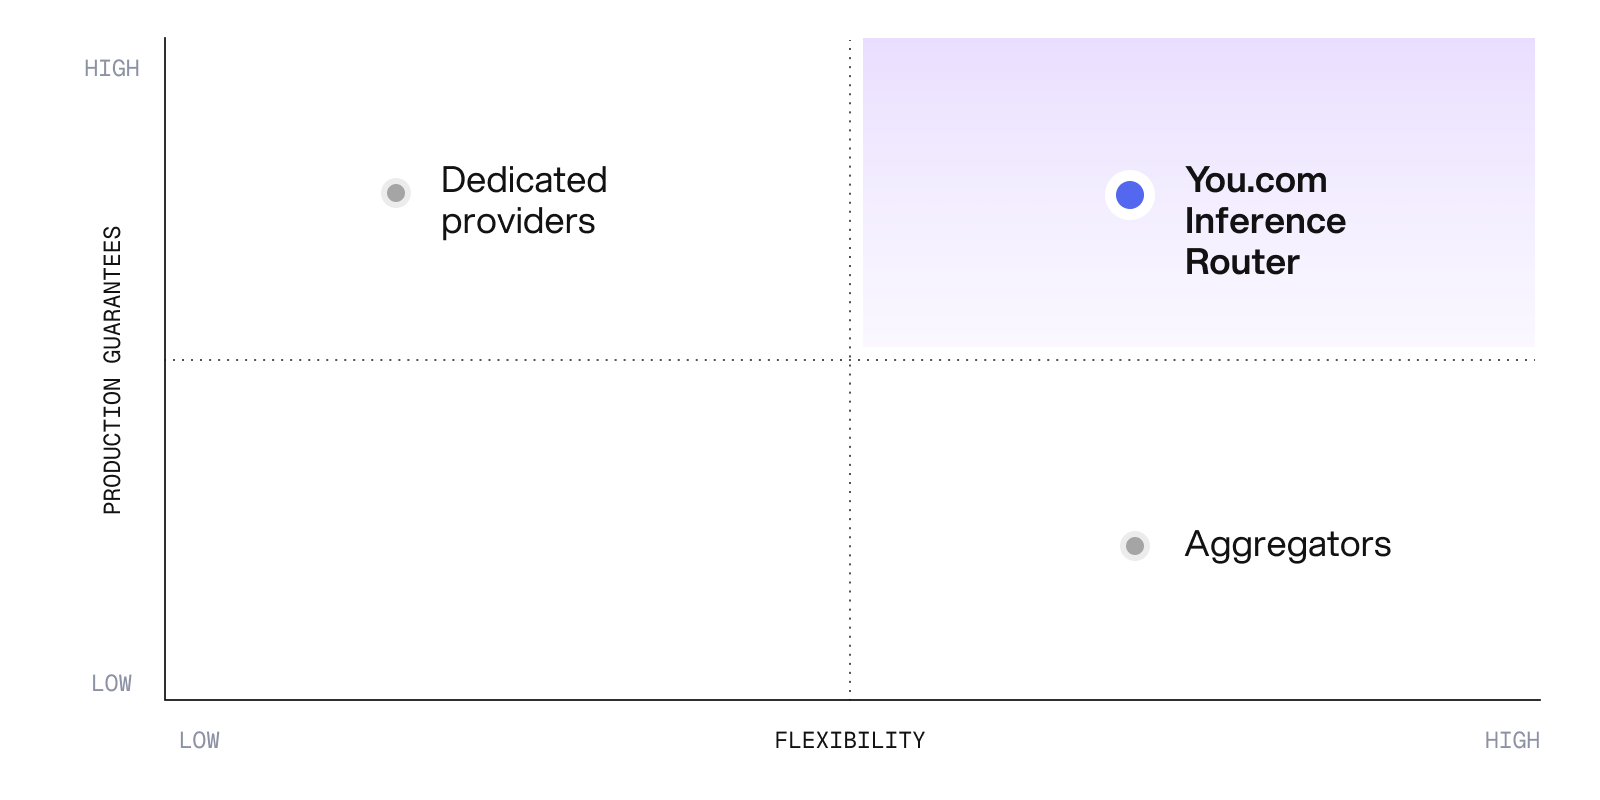
Open-weight models now handle a growing share of production work at a fraction of the cost of frontier models. Classification, extraction, summarization, routine agent steps and much of coding all run well on them today.
Teams often start by experimenting with a variety of models on OpenRouter to see what works. But once those workloads move past experimentation into real production, the requirements change: production agents need consistent uptime, predictable latency, and a clear plan for when a provider goes down.
Security is the other blocker. Before an open-weight model touches customer data, it has to pass the same review as any other vendor: ZDR, US hosting, access controls and a DPA where needed. Across a patchwork of model providers, those answers vary from one provider to the next, and often from one model to the next, so many migrations stall in security review.
Dedicated inference providers can clear these bars, but usually only with a significant upfront contract.
Inference Router makes the same reliability and security available on demand.
| Enterprise reliability and security | |||
|---|---|---|---|
| You.com | OpenRouter | Typical dedicated provider | |
| Uptime SLA with credits | At least 99.9% | No published SLA | With commitment |
| Zero data retention across model and web search | Model only; web search via third parties | Model only | |
| 100% US-hosted infrastructure | Varies by provider | ||
| Own inference capacity, with multi-provider failover | You.com Inference Direct first | Routes across third-party providers | Own capacity, single provider |
| Dedicated models and custom deployment options | |||
| DPA available | Varies | ||
| Pricing | |||
| You.com | OpenRouter | Typical dedicated provider | |
| Flexible pricing: pay-as-you-go with volume discounts as you scale | Both, with the SLA on either | SLA in enterprise agreements only | Commitment required for SLAs and support |
| No platform fee | 0% | 5.5% | |
| Web search | |||
| You.com | OpenRouter | Typical dedicated provider | |
| Models optimized with web search, through direct lab partnerships | |||
| Web search on the same server as the model | Via a third-party provider | Varies | |
| Onboarding | |||
| You.com | OpenRouter | Typical dedicated provider | |
| Guided onboarding with engineers | With a pay-as-you-go agreement | Engineering contact with enterprise agreement | Included with commitment |
See how Inference Router fits your workloads. Talk to an engineer to get started.
What we built
Inference Router gives you leading AI models through a single OpenAI-compatible API, built for teams running them in production, without a separate integration for every provider.
99.9% minimum uptime SLA
We guarantee at least 99.9% uptime, backed by service credits. For larger deployments, we offer higher uptime tiers, volume discounts and increased throughput. See live uptime.
Our own capacity, with multi-provider failover
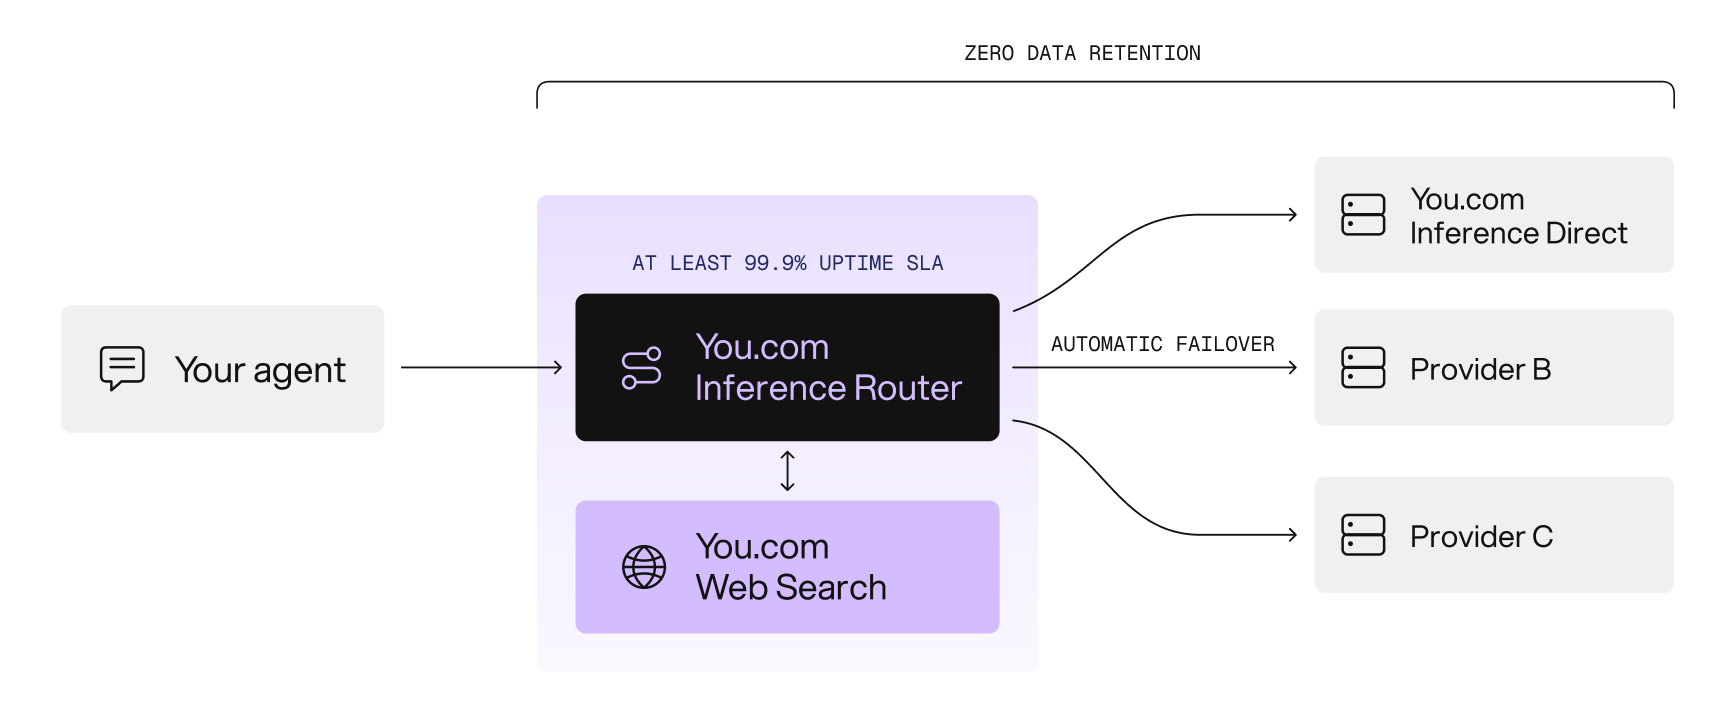
Requests go first to You.com Inference Direct, our own inference capacity, so most traffic runs on infrastructure we operate and tune ourselves. If Inference Direct is unavailable or at capacity, your request fails over automatically to a vetted partner provider, and your agent never notices.
The providers behind every request
Your requests run on You.com Inference Direct, our own capacity. If we need backup to maintain SLAs, we use a small set of trusted partners: Parasail, Wafer, Alibaba Cloud, Meta, Inception, and coming soon - Prime Intellect. Every provider is 100% US-hosted and meets our compliance requirements, including ZDR.
Full-stack ZDR
We don't store your prompts or outputs, on any model call or any web search request, so one ZDR policy covers the You.com managed stack.
100% US-hosted infrastructure
For teams with security or data residency requirements, models run on 100% US-hosted infrastructure, including failover.
Simple, predictable pricing per model
Each model has one published price per token, with no platform fee on top. Failover never changes your bill, so your spend stays predictable. Inference and web search come on one provider bill. Volume discounts are available as you scale.
Enterprise compliance controls
Every account runs on SOC 2 compliant infrastructure, with daily visibility into usage by model, cost and provider, and spend caps on each API key, so a runaway agent or test environment can't surprise you at the end of the month. Where requested, enterprise accounts add a DPA for your customer contracts.
Choose the right model for each workload
The key is choosing the model that meets the requirements of each workload, without paying for capabilities you don't need. A high-volume classification workload has different requirements from an agent that reasons across multiple steps or tackles a complex coding task.
Our curated lineup covers leading open-weight models from DeepSeek, Moonshot AI, Z.ai, Alibaba and MiniMax, alongside models from US labs like Meta and Inception. We work directly with many of the labs behind these models, which lets us run optimized endpoints for the top models and, in some cases, tune models and web search together. Every model runs on 100% US-hosted infrastructure.
| Model | Lab |
|---|---|
| Kimi K3 | Moonshot AI |
| GLM 5.3 | Z.ai |
| DeepSeek V4 Pro | DeepSeek |
| MiniMax M3 | MiniMax |
| Muse Spark 1.3 | Meta |
| Muse Wonder | Meta |
| Mercury 3 | Inception |
| GLM 5.3 Flash | Z.ai |
| DeepSeek V4.1 Flash | DeepSeek |
| Qwen 3.7 Max | Alibaba |
| Qwen 3.7 Plus | Alibaba |
| Qwen 3.8 Max | Alibaba |
| Qwen 3.8 Plus | Alibaba |
| GPT-OSS-120B | OpenAI |
Faster, more accurate agents with built-in web search
You.com has run AI and web search together in production since December 2022, when we became the first search engine to pair a large language model with live web results. That experience shapes how Inference Router works.
Web search runs on the same server as the model, so agents that need current information skip the round trip to a separate vendor. Our internal testing shows this cuts latency by up to 15%, and the savings compound for agents that search several times per task.
It changes accuracy, too. Open-weight models carry less built-in knowledge, so web search often decides whether a cheaper model is good enough. In an independent Braintrust evaluation on questions that need current information, an open-weight model with You.com web search matched or beat a leading closed model using its own built-in search, at up to 75% lower cost per question. Actual results will vary by model, task and evaluation setup. Learn more.
And because we run both layers, we can improve them together. In joint work with NVIDIA and CoreWeave, post-training NVIDIA Nemotron 3.5 Lightning with You.com web search in the training loop improved BrowseComp accuracy from 36.97% to 45.45% while cutting tool calls by 30%. Learn more.
Guided onboarding, from first call to production
Get started on your own in the playground, or talk to an engineer. We’ll start with an onboarding call to review your workloads and recommend a model for each. For larger deployments, our engineers work with you hands-on, testing performance against your real inputs and planning the migration with you.
Try it in the playground or talk to an engineer to get started.
Production-grade inference on demand
If you're already running AI applications in production, a useful starting point is to identify workloads where open-weight models could meet your performance requirements at a lower cost. Test those workloads against representative inputs, account for web search requirements, and estimate the impact at your expected usage volume.
Then change one base URL, and your existing OpenAI-compatible code runs on Inference Router.
Try it in the playground or talk to an engineer to get started.
LI Test
LI Test
Share Article:
Related resources.
What Is Agentic Resource Discovery? Machine-Readable Access for AI Agents
October 9, 2026
Blog
How to Build a Multi-Tenant Search API Layer with the You.com Web Search API
October 9, 2026
Blog

How to Build a CVE Monitoring Pipeline with the You.com Web Search and Contents APIs
October 8, 2026
Blog

How to Build a Breach Monitoring Pipeline with the You.com Web Search and Contents APIs
October 8, 2026
Blog
What Is an AI Search API? A Practical Guide for Developers Building AI Applications
September 30, 2026
Blog